CoursesLLMs for mobile engineers, from tokens to your app
Puzzle 8 · 9 of 10
Find evidence before asking the model
A support assistant needs the correct help article. Compare two ways to select it for the same question.
All puzzles in this course
The problem
The help article says “register an authenticator app.” A reader asks “Can I require an extra proof of who I am when I log in?” What text should the app add to the model call?
See it
Scroll sideways to see the full diagram.
The reader describes an extra proof of identity.
Step 1 of 4The app has a small collection of help articles.
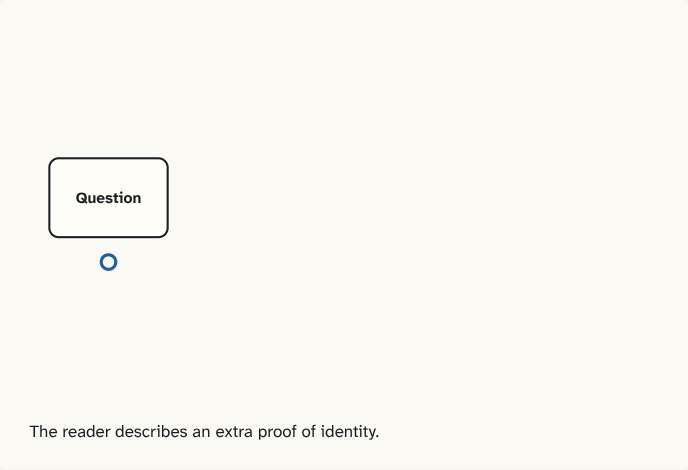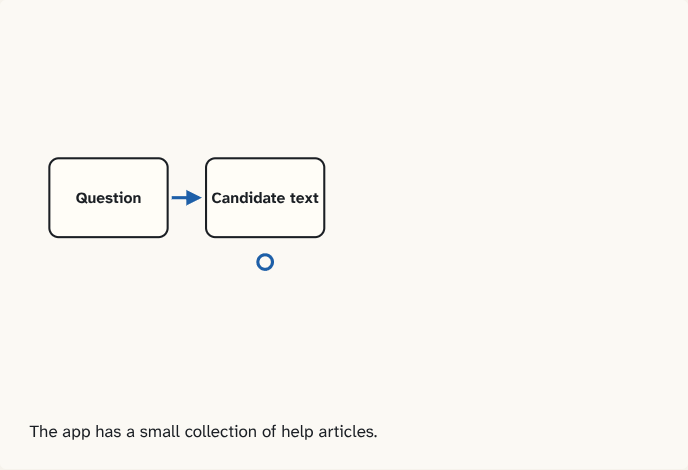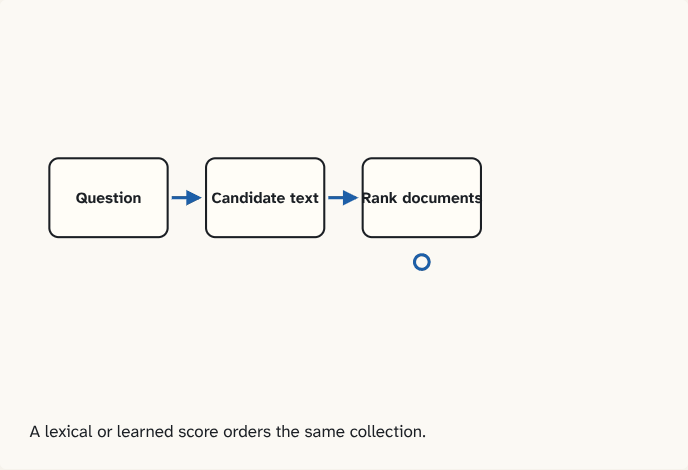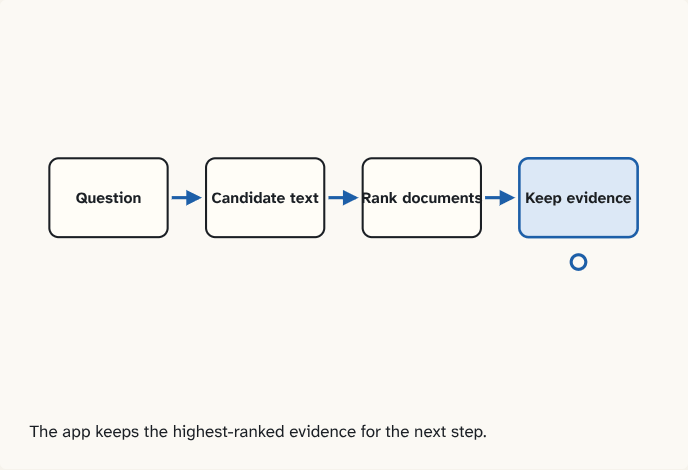
Step 2 of 4A lexical or learned score orders the same collection.
Step 3 of 4The app keeps the highest-ranked evidence for the next step.
Step 4 of 4
The building block
Retrieval selects candidate text from a collection before the application asks a model to answer. The query and every article get a score. Only the highest-ranked articles are passed along.
One approach, TF-IDF, measures how strongly words characterize each document. Common words receive less weight than words that are unusual in the collection. A short question and article can rank well if they share distinctive wording.
An embedding is a list of numbers produced by a model trained to represent text. The application can compare the direction of query and article vectors using cosine similarity. Related phrasing can end up close together even when it uses different words.
I compared both methods for twelve English questions against the same eight synthetic help articles. The expected document was assigned before running the comparisons.
| Query set | TF-IDF first result | MiniLM first result |
|---|---|---|
| Six questions with similar wording | 6/6 | 6/6 |
| Six paraphrases | 1/6 | 6/6 |
| All twelve | 7/12 | 12/12 |
This run measures selection in a tiny collection. Neither method here generated an answer. The result is an example of why to measure paraphrases on your own documents.
Go deeperWhat happens with an exact reference number?
A user quotes a rare error identifier exactly. Is there a reason to keep lexical matching in the comparison?
A rare, exact identifier is a strong lexical signal. The paraphrase results tell us nothing about how either method ranks unseen identifiers, so add exact-identifier cases to the test set.
Check yourself
Sources
What you now know
Retrieval selects evidence before generation. Word overlap and learned vectors can rank the same documents differently, especially when a query changes its wording.
Answer every question above correctly to unlock the next puzzle.
Something wrong or unclear on this page? Tell me: a puzzle that didn't click is a bug in the puzzle.