LLMs for mobile engineers, from tokens to your app · Puzzle 4 · 5 of 8
It remembers nothing
Your chatbot answers the first question well, then forgets it on the second. Or it remembers everything, and each message gets slower and more expensive. Both come from one fact about the API. Here's what your app must send, every time.
The problem
Your first version sends only the user's latest message. The bot answers "What's its battery life?" with "What device do you mean?", though the user named it one message earlier. Your fix sends the whole chat each time, and after fifty messages each reply is slower and costs ten times more. What's going on?
See it
The app sends only the latest message. The model has never seen the earlier one: the API is stateless.
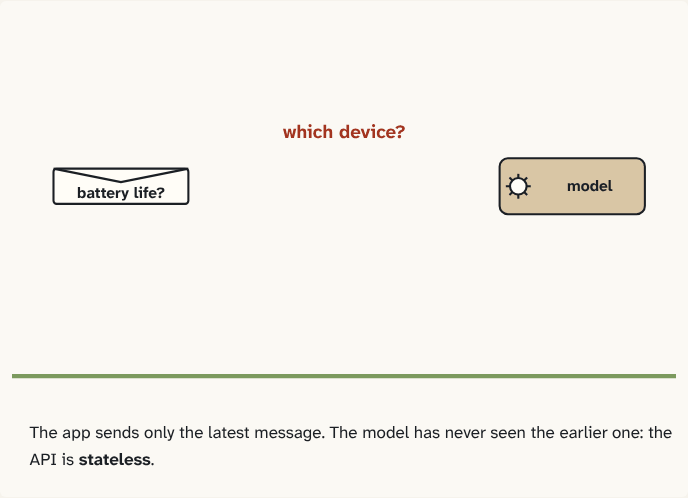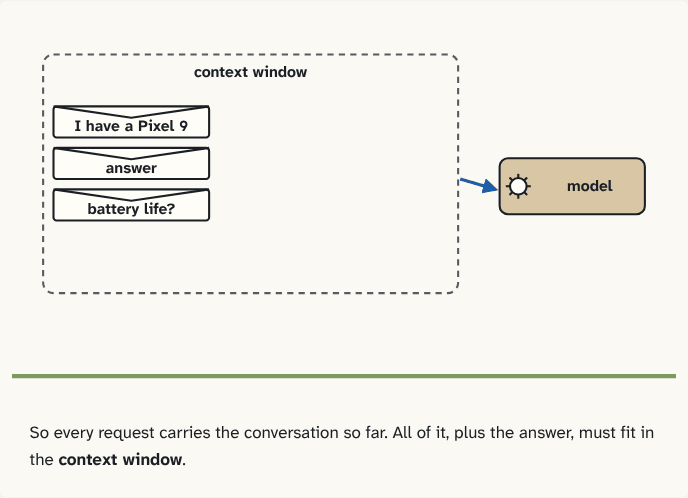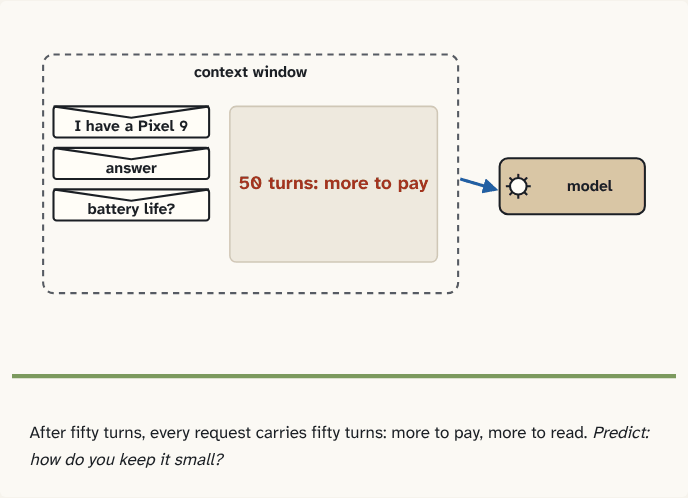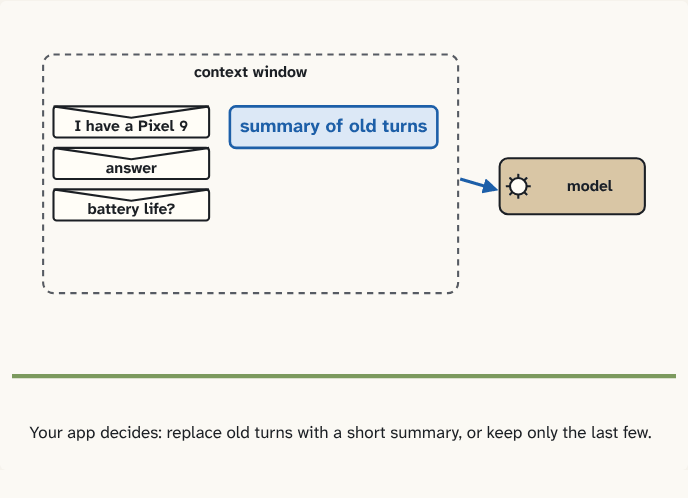
Step 1 of 4So every request carries the conversation so far. All of it, plus the answer, must fit in the context window.
Step 2 of 4After fifty turns, every request carries fifty turns: more to pay, more to read. Predict: how do you keep it small?
Step 3 of 4Your app decides: replace old turns with a short summary, or keep only the last few.
Step 4 of 4
The building block
The model API is stateless: each request starts from nothing. There's no session, no memory kept on the server between your requests, holding your conversation. If the model is to "remember" an earlier message, that message must be in this request.
So a chat app keeps the conversation itself, in its ViewModel or database, and sends all of it with every new message: earlier user messages, earlier answers, then the new message.
Everything in one request, plus the answer the model writes, must fit in the context window: the model's working memory for that request, measured in tokens. Windows are large now, but three things grow with every message:
- Cost: you pay for all the input tokens again, every turn, so a chat's total cost grows faster than its length. Prompt caching makes a repeated beginning cheaper and faster to read, but you still send it.
- Time: more input to read before the first token (puzzle 3).
- Quality: Anthropic notes that as the token count grows, accuracy and recall degrade.
So long chats need a policy: keep the last few turns, replace old ones with a short summary, or drop what doesn't matter. That's your code's decision, not the model's.
The analogy
A brilliant consultant with no memory at all. Every time you call, you read them the whole file so far, then ask your question. A thicker file takes longer to read, costs more of their time, and eventually they skim.
Check yourself
Sources
- Anthropic: Working with the Messages API ("The Messages API is stateless, which means that you always send the full conversational history to the API.")
- Anthropic: Context windows (the context window is "a 'working memory' for the model"; "As token count grows, accuracy and recall degrade, a phenomenon known as context rot")
What you now know
The model API is stateless: it remembers nothing between requests, so the app sends the whole conversation every time. Everything sent, plus the answer, must fit in the context window, the model's working memory for that request. Long chats cost more per message and can degrade, so trim, summarise or drop old turns on purpose.
Answer every question above correctly to unlock the next puzzle.
Something wrong or unclear on this page? Tell me: a puzzle that didn't click is a bug in the puzzle.